AI at the core of building the next generation of models.
Up to 2,000 tokens per second for high-speed inference.
Frontier intelligence, open to build on.
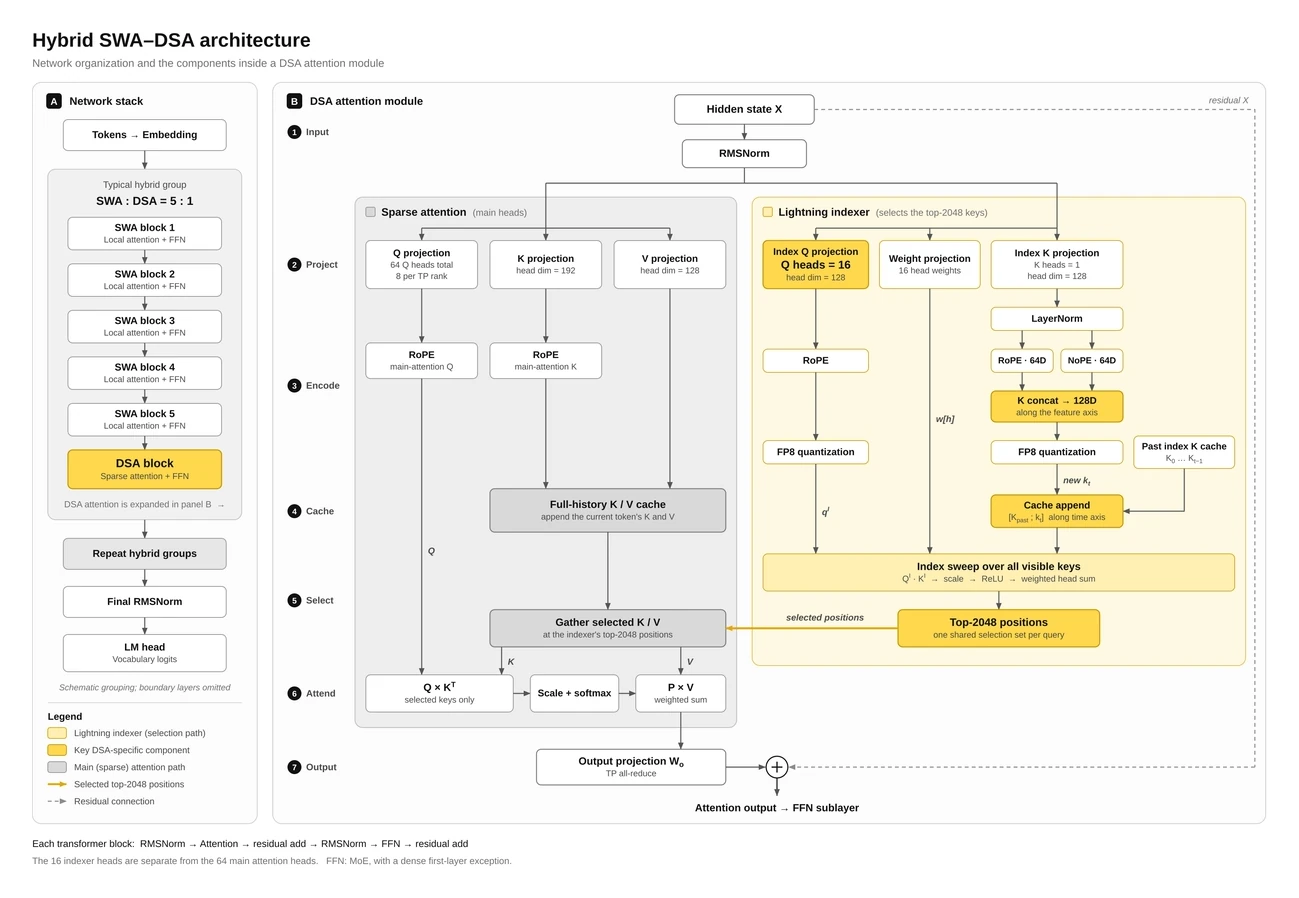
An open-weight 309B MoE model for coding and AI R&D, with native 1M context, no full attention, and AI-optimized inference up to 2,000 tokens/s.
Access the model through our developer platform.
Download the open weights and model card.